How to practice coding challenges with your AI coding agent
Solve a real challenge on your own machine with Claude Code, Cursor or Codex, then get the whole session scored across Direction, Outcome and Lift.
Pick a real, ticket-sized challenge, solve it on your own machine with the agent you already use (Claude Code, Cursor or Codex), and have the whole session scored: your prompts, commits and test runs, not just the final code. On kodwai that is two commands, npx @kodwai/cli challenge <slug> to start and npx @kodwai/cli submit to finish, and the score is split across three axes: Direction, Outcome and Lift.
What does practicing with your own agent look like?
A useful practice loop has four parts. A problem with a written spec, starter files and tests. A time limit. Your own editor and your own agent. And a git history you can read afterwards to see what you actually did.
That is different from algorithm drills in a browser editor. Those test what you remember. This tests how you direct the work: how you brief the agent, how you check what it gives back, and what you do when it goes the wrong way.
kodwai is a platform where developers solve real coding challenges on their own machine with their own AI coding agent (Claude Code, Cursor, or Codex) and get scored on how well they direct the agent, across three axes: Direction, Outcome, and Lift.
You can browse everything on the public challenge list.
How do you start one?
Pick a challenge, run the CLI and choose your agent, solve on your own machine, submit with one command, get your score.
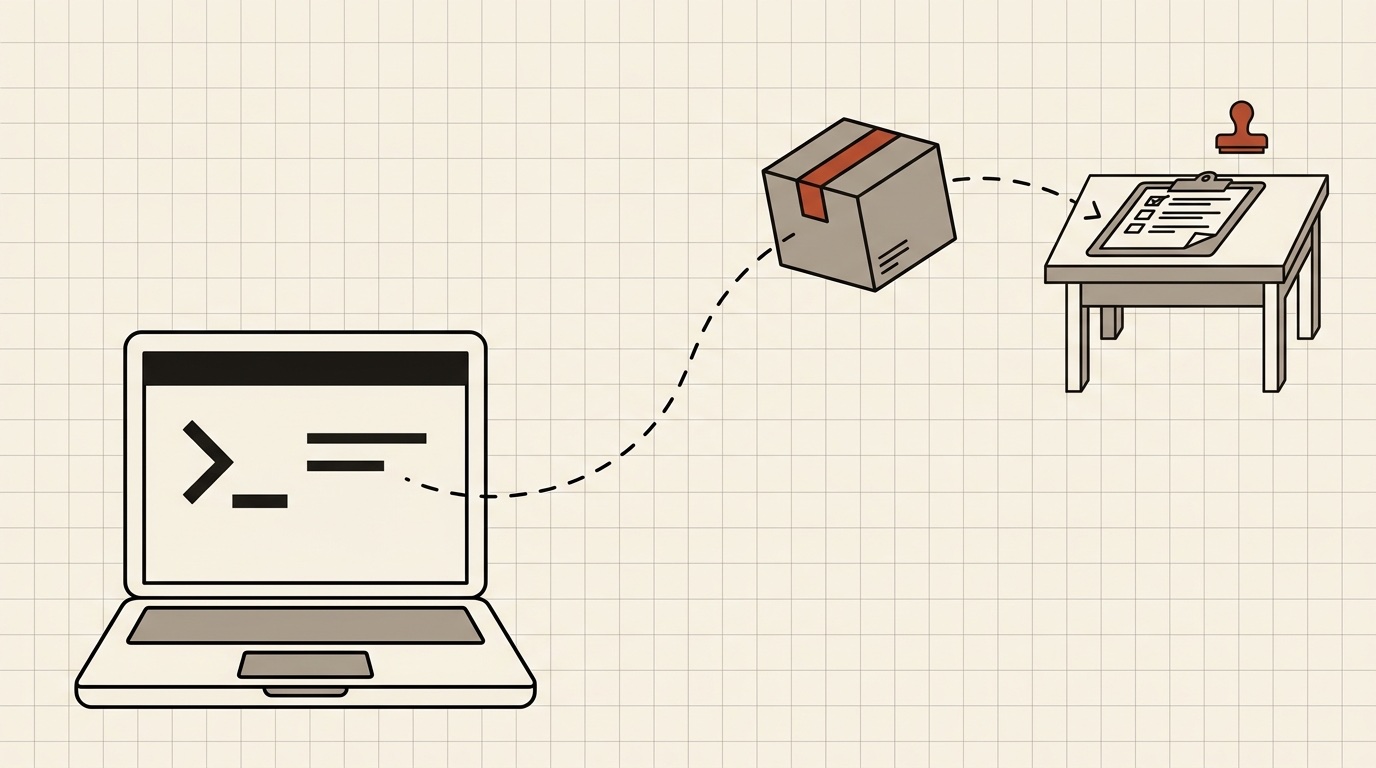
npx @kodwai/cli challenge bookshelf-rest-api
That signs you in through the browser if needed, asks which agent you will use, downloads PROBLEM.md, starter files and tests, initializes a git repo and starts the timer. bookshelf-rest-api is the starter challenge: easy, backend, 60 minutes.
When you are done, from the challenge folder:
npx @kodwai/cli submit
That sends your code, git history, test runs, the agent transcript and the time taken. The CLI only collects from the challenge workspace, nothing from your other projects. You need Node.js 20+ and git.
There is no browser sandbox. You work in your own terminal, with your own setup.
How is the session scored?
The score is kodwai's AI Collaboration Score for coding agents, calibrated 0 to 100. Here is how the score is defined. It has three axes:
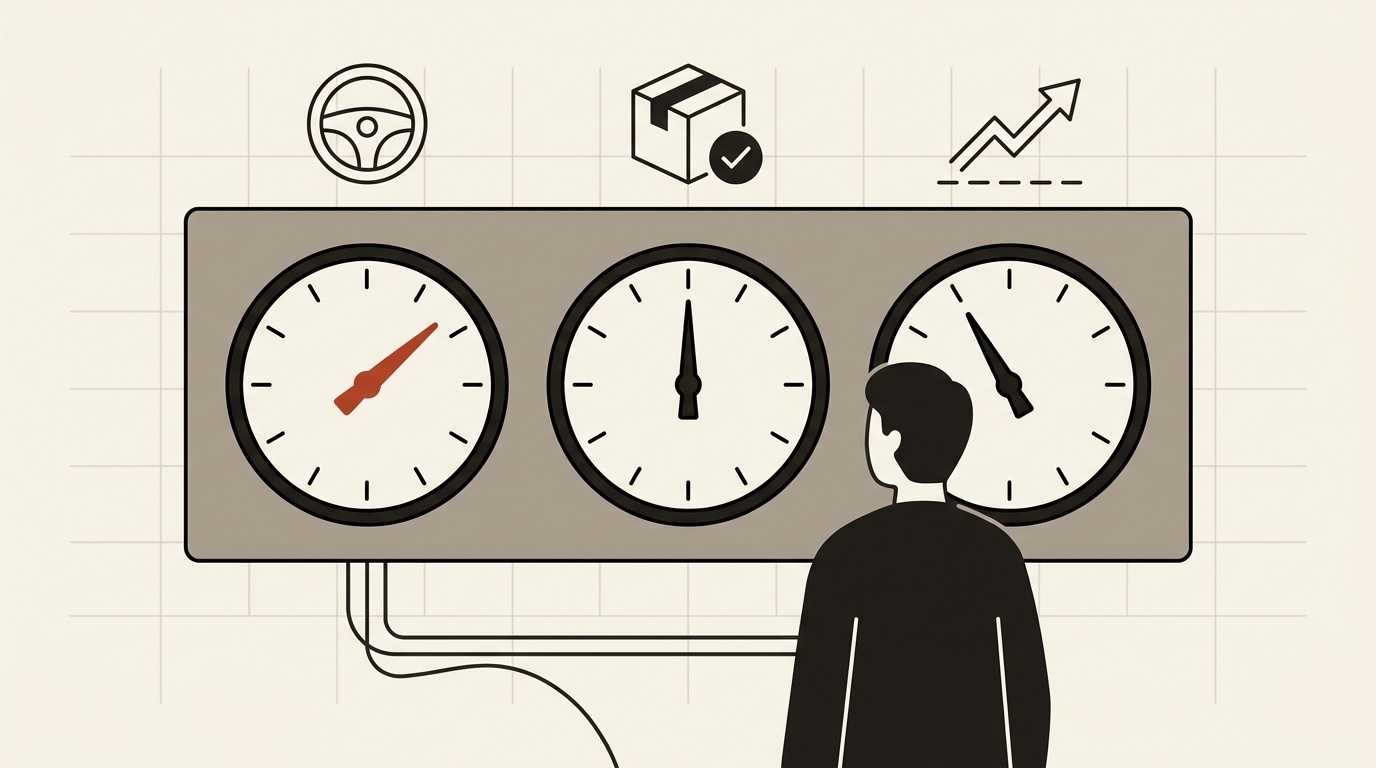
- Direction: how you steer, verify, and decompose.
- Outcome: what shipped, replayed and stress-tested to prove it holds.
- Lift: how far you beat a solo AI, not just that you passed.
Passing tests is necessary but not sufficient. Every signal cites its own evidence from your transcript, commits, and test runs, and your score comes with a confidence interval instead of false precision.
Direction is made of six signals. They double as a checklist for your next session:
- Spec Precision: write the constraints and edge cases down before the first prompt.
- Verification Rigor: read what the agent produced and push back when it is wrong.
- Decomposition: break the work into ordered steps instead of one giant prompt.
- Recovery: when the agent drifts, catch it early and redirect.
- Intent Fidelity: make sure what got built is what you asked for.
- Engagement: stay in the loop and iterate instead of pasting the spec and walking away.
What I learned scoring my own sessions
Here's what it looked like for me. I ran two of the hard challenges in Claude Code: the production RAG service with an eval harness and cost guardrails, and the multi-tenant rate limiter. These are two separate sessions, not a trend. One scored 84 and the other 95. The signals that moved most were Spec Precision and Recovery. Writing the constraints and edge cases down before the first prompt paid off, and so did catching the agent early when it drifted instead of letting it run. Next time I'd spend even more of the first few minutes on the spec, because every minute there saved me more than a minute of cleanup later.
How is this different from LeetCode-style practice?
LeetCode and similar sites have enormous problem sets and communities, and they are the standard for classic algorithm interview prep. kodwai does not test memorized algorithms. It scores how you direct an AI agent through ticket-sized work.
If you have a classic algorithm round coming up, practice on LeetCode. If you want to get better at the way most of us write code now, with an agent, practice that directly.
If you are on the other side of the table, I wrote a separate post on how to interview developers who work with AI agents.
What does it cost?
Solving challenges, the score, the public profile and the leaderboard are free for developers. Every account gets 3 free submissions scored on kodwai's own Anthropic key. After that you connect your own Anthropic API key in Settings for unlimited submissions. The key is encrypted at rest and only used to score your own work.
Try one
npx @kodwai/cli challenge bookshelf-rest-api
Or pick your own from the challenge list.
How this was made
The section on my own sessions is based on my two runs. Claude drafted the rest from the kodwai fact sheet and a content brief, using the live challenge, score definition and hiring pages as read on 2026-09-26.
try it yourself
Reading about it is the easy part.