How do I set up a coding challenge that a coding agent can work on?
What a coding challenge needs so an agent can work on it, what to measure besides passing tests, and a 60 minute challenge you can run today.
How do I set up a coding challenge that a coding agent can work on?
By Hakan Karaagac
Give the agent four things: a written spec, a test suite it can run, a time limit and a git repo. Then judge the run on more than "did the tests pass". An agent can turn tests green while the person steering it did a poor job.
Below is a short checklist, a way to score the result, and a real challenge you can run in 60 minutes.
What does a challenge need so an agent can work on it?
Imagine handing a task to a contractor on day one. They cannot ask you questions. What do they need on the desk? Five things do most of the work.
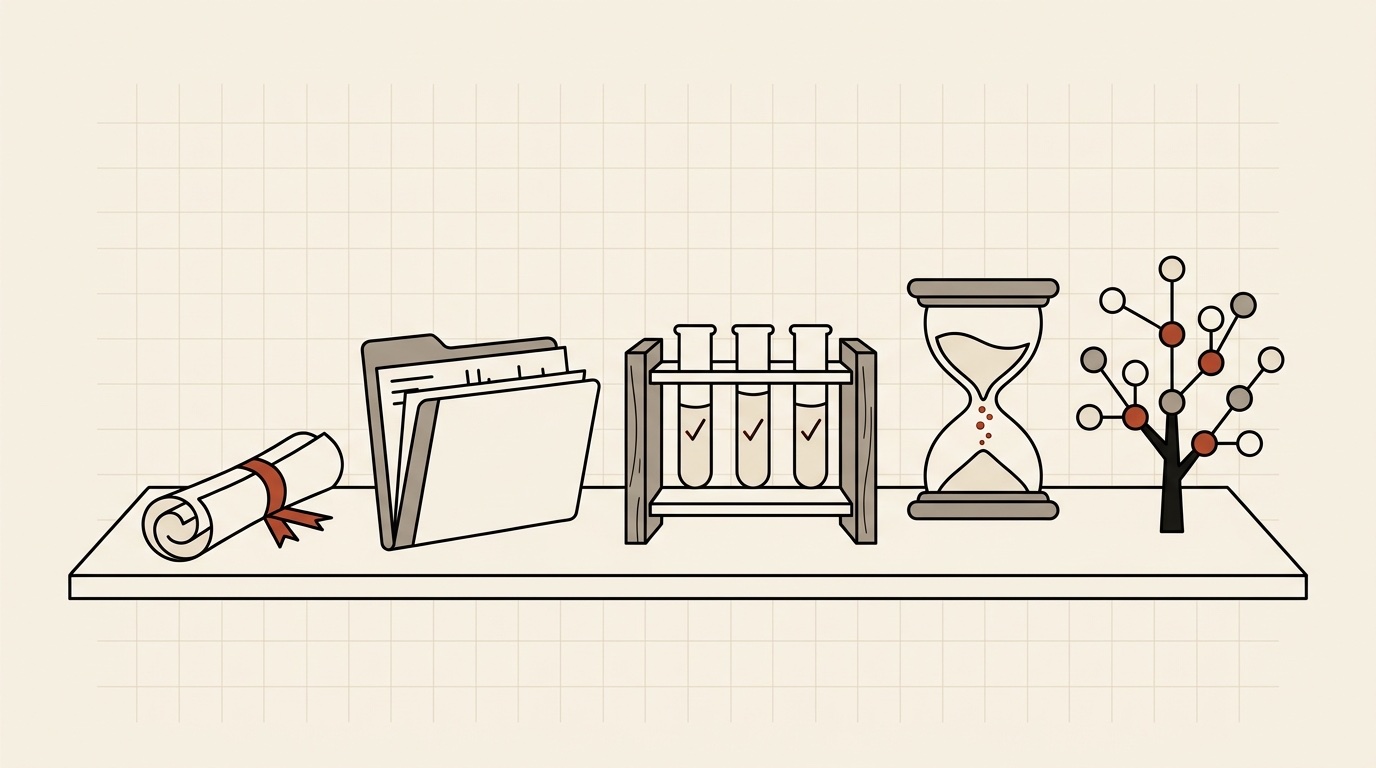
- A written spec in the repo. The agent reads files, not minds. Put the task in a
PROBLEM.mdnext to the code. - Starter files. Give the agent something to extend. A real codebase tests judgment. A blank folder tests typing.
- Tests the agent can run. If it cannot run the tests, it cannot check its own work, and you cannot tell whether it tried.
- A time limit. A clock turns "do it well" into "decide what matters first".
- A git repo from minute one. The history shows how the work was split up and how the agent recovered from a wrong turn.
This is a starting list, not a standard. Adjust it to your own tasks.
What should you measure?
Passing tests is necessary, but it is not enough. Two people can reach green with the same agent. One writes a precise spec, checks every change and catches a bad assumption. The other pastes the task in and accepts whatever comes back. Same result on the test report, very different skill.
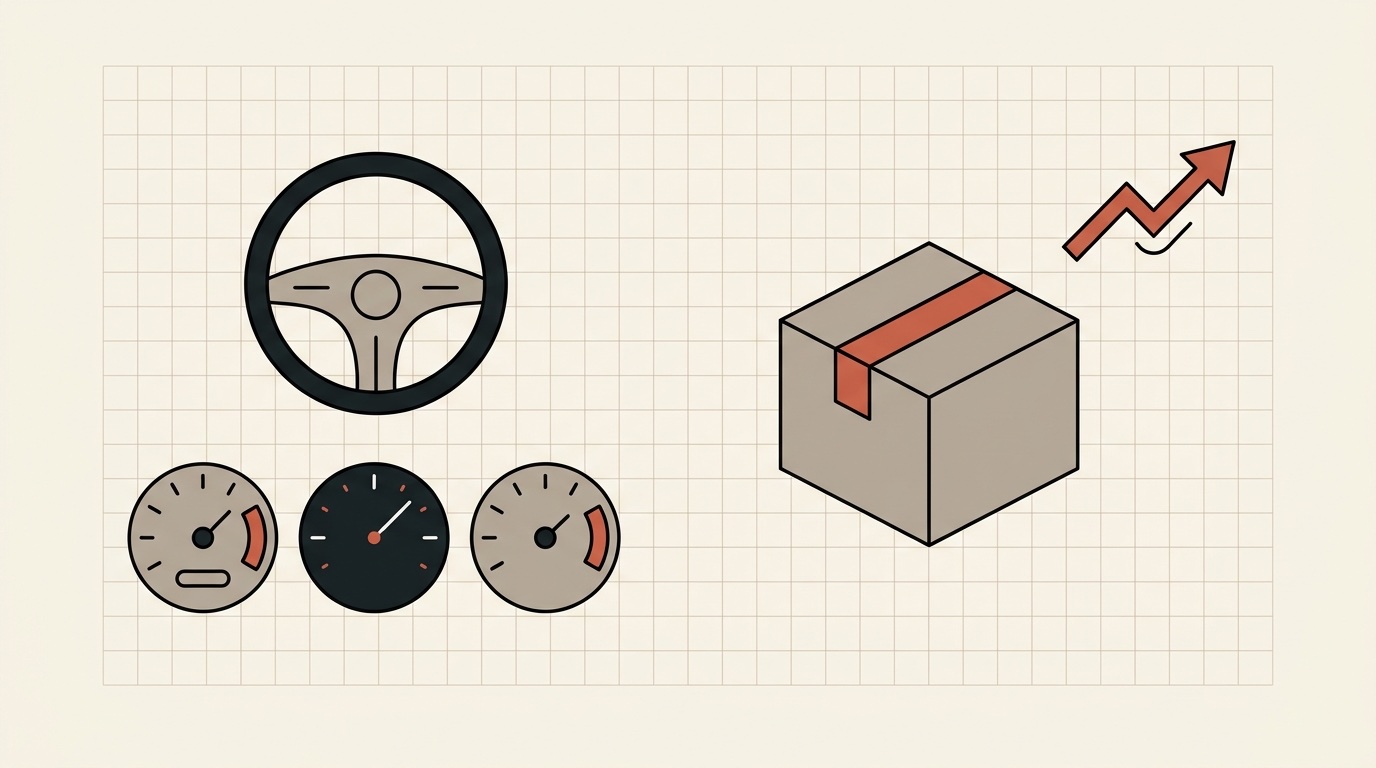
kodwai scores a run on three axes:
- Direction: how you steer, verify and decompose the work.
- Outcome: what shipped, replayed and stress-tested to prove it holds.
- Lift: how far you beat a solo AI, not just that you passed.
You do not need kodwai's scoring to use the idea. When you review a run, ask three questions. How did the person direct the agent? What actually shipped? Did the person add anything the agent would not have done alone? If you only read a green test report, you are measuring the agent.
What does a ready-made challenge look like?
kodwai is a platform where developers solve real coding challenges on their own machine with their own AI coding agent (Claude Code, Cursor, or Codex) and get scored on how well they direct the agent, across three axes: Direction, Outcome, and Lift.
The starter challenge is bookshelf-rest-api. It is easy, backend, and takes 60 minutes. Start it with one command:
npx @kodwai/cli@latest challenge bookshelf-rest-api
Here is what the command does. It signs you in through the browser if needed. It asks which agent you use. It creates the workspace and starts the timer. The workspace holds PROBLEM.md, the starter files and the tests, and it is already a git repo. You solve it on your own machine with your own agent. There is no browser sandbox.
When you are done, run:
npx @kodwai/cli@latest submit
That packages your code, git history, test runs, the agent transcript and the time taken, and kodwai scores them. Every developer account gets 3 free submissions scored on kodwai's own key. After that, you add your own Anthropic API key in Settings. You need Node.js 20+ and git.
What should you do next?
Run the starter once before you design your own. Watching an agent work on a task teaches you more about what it needs than any checklist.
- Run
npx @kodwai/cli@latest challenge bookshelf-rest-apiand pick the agent you use every day. - Read
PROBLEM.mdthe way the agent will, with no context beyond the page. - Submit with
npx @kodwai/cli@latest submitand read what each axis says about your run. - Write your own spec, tests and time limit using the checklist above.
You can browse more on the challenges page. If you lead an engineering team and want a custom project for candidates, see the hiring track: custom interview projects, a one-link invite, and candidates solve them locally in Claude Code.
Limits of this post
This post does not compare agents or models, and nothing in it comes from kodwai usage data. It is a how-to, not a benchmark.
try it yourself
Reading about it is the easy part.